My name is Haowen Bai (白浩闻). I am currently a Postdoctoral Research Fellow at Nanyang Technological University, Singapore, supervised by Prof. Yap Kim Hui.
I received my Ph.D. degree in Statistics from School of Mathematics and Statistics, Xi’an Jiaotong University, supervised by Prof. Jiangshe Zhang and worked closely with Dr. Zixiang Zhao and Assoc. Prof. Shuang Xu.
My research focuses on low-level computer vision and multi-source information fusion, with a particular emphasis on multi-modal image fusion and restoration.
Email:
haowen.bai (at) ntu.edu.sg
haowen.bai (at) hotmail.com
我是白浩闻,现在是新加坡南洋理工大学的博士后研究员,合作导师是 Yap Kim Hui 教授。
我在西安交通大学数学与统计学院获得统计学博士学位,导师是张讲社教授。读博期间,我与赵子祥博士和徐爽副教授有密切合作。
我的研究方向是底层计算机视觉和多源信息融合,重点关注多模态图像融合与图像复原。
邮箱:
haowen.bai (at) ntu.edu.sg
haowen.bai (at) hotmail.com
Last updated: 2026-11-20最近更新:2026-11-20
🔥 News
- 2025.09: One paper on video fusion is accepted by NeurIPS 2025 (Spotlight).
- 2025.06: Two papers are accepted by ICCV 2025 (One on retinex-based image fusion and the other on hyper-spectral image restoration).
- 2025.02: One paper on multi-modality image fusion is accepted by CVPR 2025 (Highlight).
🔥 新闻
- 2025.09:一篇视频融合论文被 NeurIPS 2025 接收(Spotlight)。
- 2025.06:两篇论文被 ICCV 2025 接收,一篇是基于 Retinex 的图像融合,另一篇是高光谱图像复原。
- 2025.02:一篇多模态图像融合论文被 CVPR 2025 接收(Highlight)。
📖 Education and Experience
- 2025 - Present, Research Fellow, School of Electrical and Electronic Engineering, Nanyang Technological University.
- 2020 - 2025, Ph.D. in Statistics, Xi’an Jiaotong University.
- 2016 - 2020, B.S. in Information and Computing Science, Dalian University of Technology.
📖 教育与工作经历
- 2025 - 至今,博士后研究员(Research Fellow),南洋理工大学电气与电子工程学院。
- 2020 - 2025,统计学博士,西安交通大学。
- 2016 - 2020,信息与计算科学学士,大连理工大学。
📝 Publications论文
For the full list of papers, see Google Scholar (citations: 3396).完整的文章列表见谷歌学术(总引用:3396)。
First-Author第一作者

Retinex-MEF: Retinex-based Glare Effects Aware Unsupervised Multi-Exposure Image Fusion
IEEE/CVF International Conference on Computer Vision (ICCV), 2025.
Haowen Bai, Jiangshe Zhang*, Zixiang Zhao*, Lilun Deng, Yukun Cui, Shuang Xu
- Retinex Theory–Based Adaptive Solution for Multi-Exposure Image Fusion, by modeling glare effects to adapt to overexposed conditions.基于 Retinex 理论的自适应多曝光图像融合方法:通过建模眩光效应来适应过曝场景。
BibTeX
@inproceedings{bai2025retinex,
  title     = {Retinex-MEF: Retinex-based Glare Effects Aware Unsupervised Multi-Exposure Image Fusion},
  author    = {Bai, Haowen and Zhang, Jiangshe and Zhao, Zixiang and Deng, Lilun and Cui, Yukun and Xu, Shuang},
  booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV)},
  pages     = {7251--7261},
  year      = {2025},
  doi       = {10.1109/iccv51701.2025.00681}
}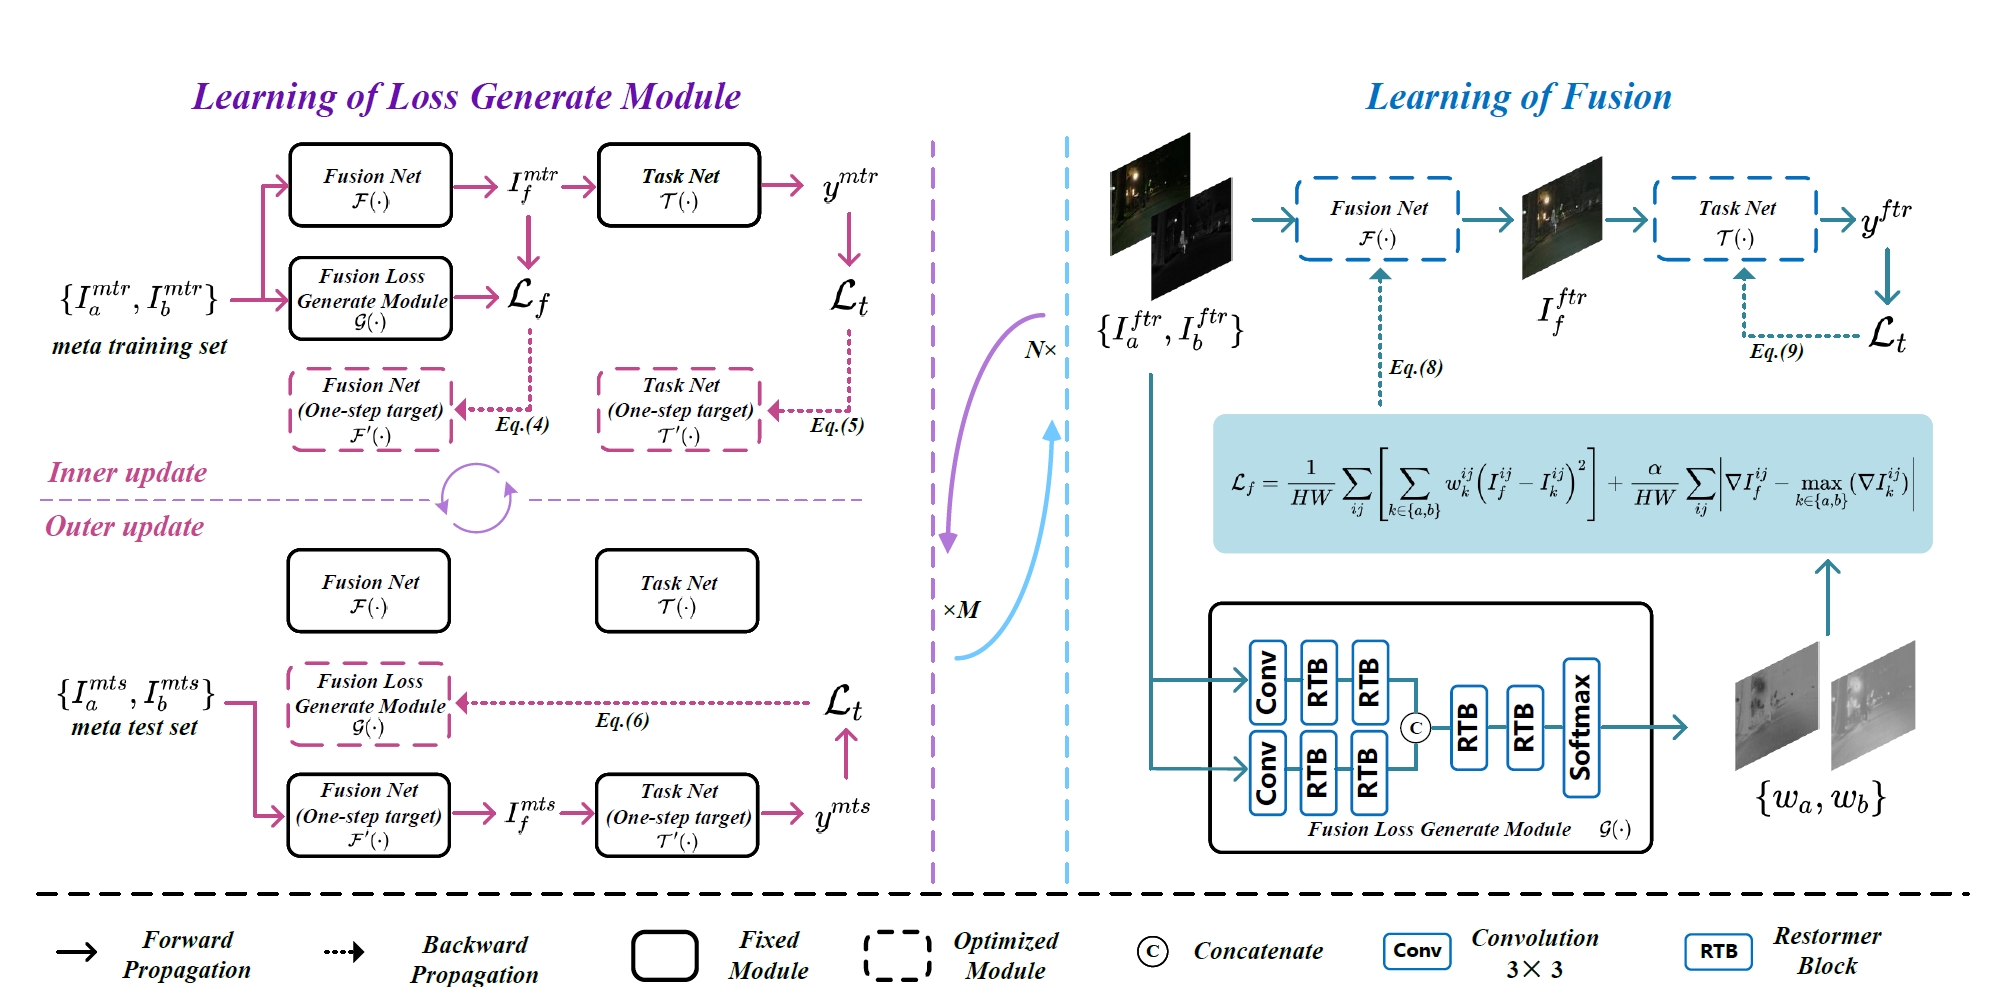
Task-driven Image Fusion with Learnable Fusion Loss
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025. (Highlight)
Haowen Bai, Jiangshe Zhang*, Zixiang Zhao*, Yichen Wu, Lilun Deng, Yukun Cui, Tao Feng, Shuang Xu
- A task-driven image fusion framework that employs a learnable fusion loss guided by downstream task objectives through meta-learning, enabling adaptive fusion optimization for improved performance in downstream tasks.任务驱动的图像融合框架:通过元学习,让下游任务的目标来指导一个可学习的融合损失,使融合自适应地优化,从而提升下游任务的表现。
BibTeX
@inproceedings{bai2025task,
  title     = {Task-driven Image Fusion with Learnable Fusion Loss},
  author    = {Bai, Haowen and Zhang, Jiangshe and Zhao, Zixiang and Wu, Yichen and Deng, Lilun and Cui, Yukun and Feng, Tao and Xu, Shuang},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  pages     = {7457--7468},
  year      = {2025},
  doi       = {10.1109/cvpr52734.2025.00699}
}
Deep Unfolding Multi-modal Image Fusion Network via Attribution Analysis
IEEE Transactions on Circuits and Systems for Video Technology (TCSVT), 35(4), pp. 3498-3511, 2025.
Haowen Bai, Zixiang Zhao, Jiangshe Zhang*, Baisong Jiang, Lilun Deng, Yukun Cui, Shuang Xu, Chunxia Zhang
- An attribution-guided fusion framework that optimizes multi-modal image synthesis for semantic segmentation via unfolding networks and adaptive loss design, prioritizing task-critical features through attribution maps.归因引导的融合框架:借助展开网络和自适应损失,面向语义分割优化多模态图像融合,并用归因图优先保留对任务关键的特征。
BibTeX
@article{bai2025deep,
  title   = {Deep Unfolding Multi-Modal Image Fusion Network via Attribution Analysis},
  author  = {Bai, Haowen and Zhao, Zixiang and Zhang, Jiangshe and Jiang, Baisong and Deng, Lilun and Cui, Yukun and Xu, Shuang and Zhang, Chunxia},
  journal = {IEEE Transactions on Circuits and Systems for Video Technology},
  volume  = {35},
  number  = {4},
  pages   = {3498--3511},
  year    = {2025},
  doi     = {10.1109/tcsvt.2024.3507540}
}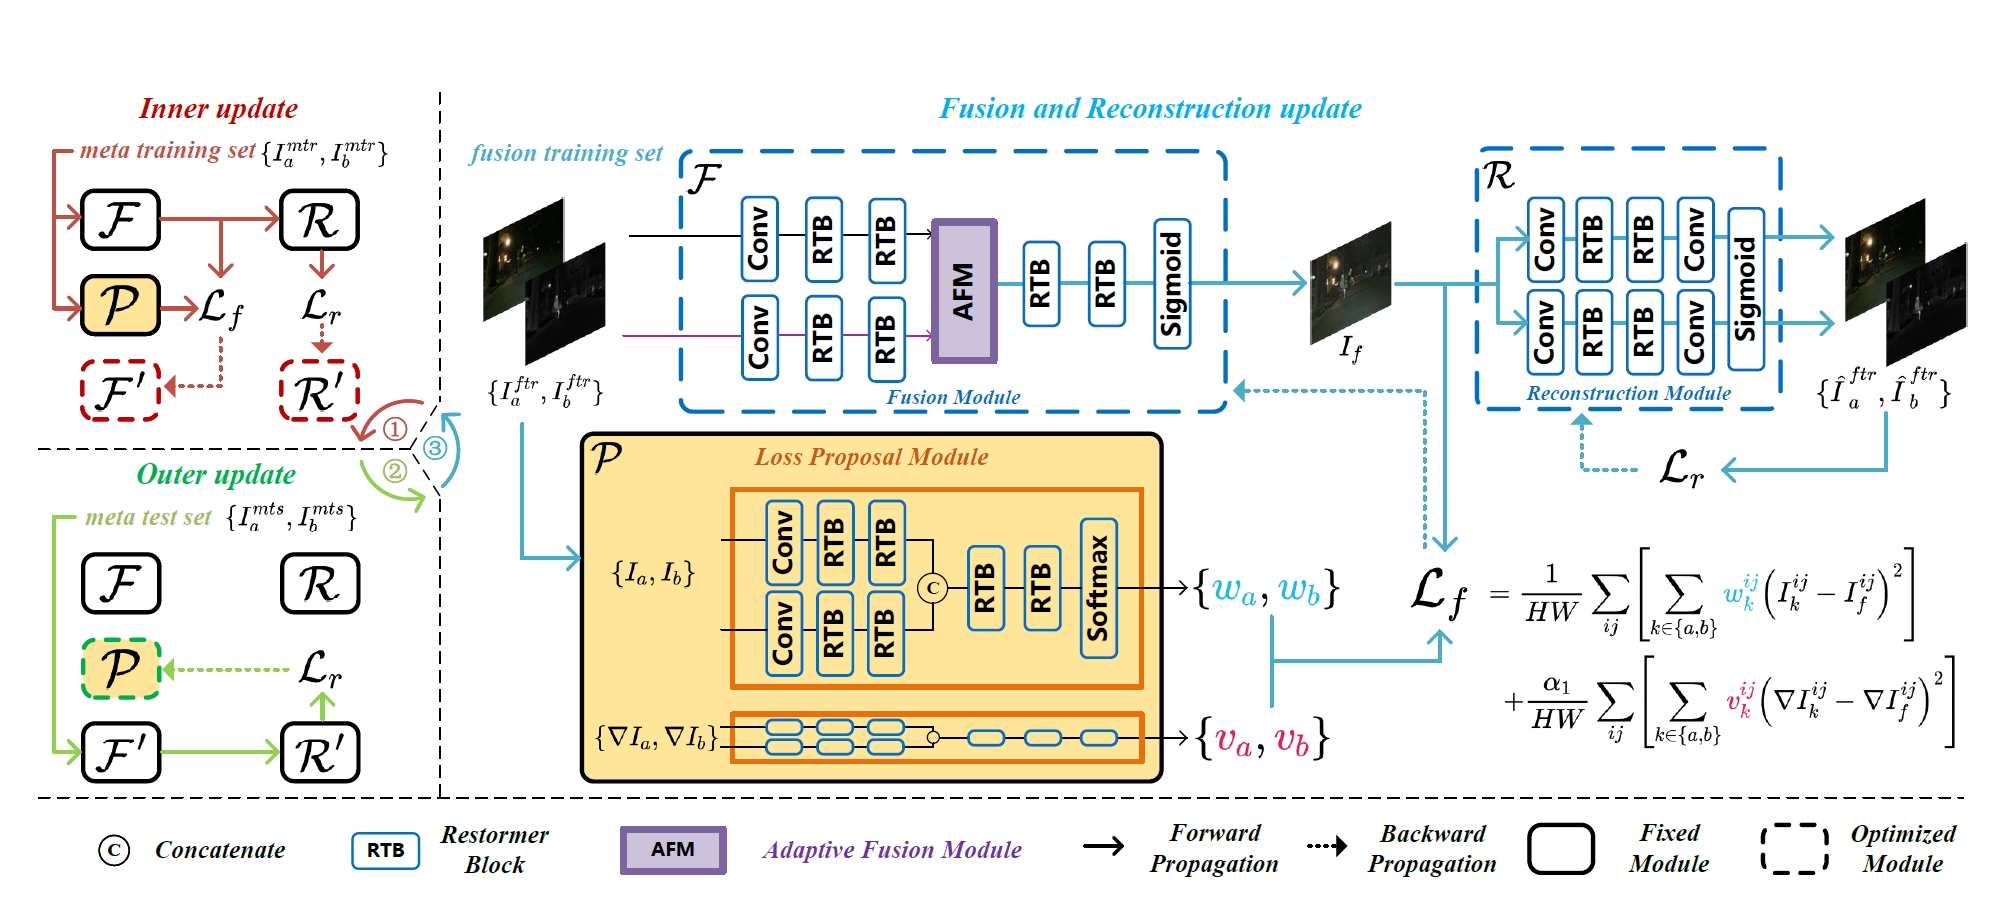
ReFusion: Learning Image Fusion from Reconstruction with Learnable Loss Via Meta-Learning
International Journal of Computer Vision (IJCV), 133(5), pp. 2547-2567, 2024.
Haowen Bai, Zixiang Zhao*, Jiangshe Zhang*, Yichen Wu, Lilun Deng, Yukun Cui, Baisong Jiang, Shuang Xu
- Propose a meta-learning-based image fusion framework that dynamically optimizes task-specific loss functions through source image reconstruction to preserve optimal source information.提出基于元学习的图像融合框架:通过重建源图像,动态优化与任务相关的损失函数,尽可能保留源图像中的信息。
BibTeX
@article{bai2024refusion,
  title   = {ReFusion: Learning Image Fusion from Reconstruction with Learnable Loss Via Meta-Learning},
  author  = {Bai, Haowen and Zhao, Zixiang and Zhang, Jiangshe and Wu, Yichen and Deng, Lilun and Cui, Yukun and Jiang, Baisong and Xu, Shuang},
  journal = {International Journal of Computer Vision},
  volume  = {133},
  number  = {5},
  pages   = {2547--2567},
  year    = {2024},
  doi     = {10.1007/s11263-024-02256-8}
}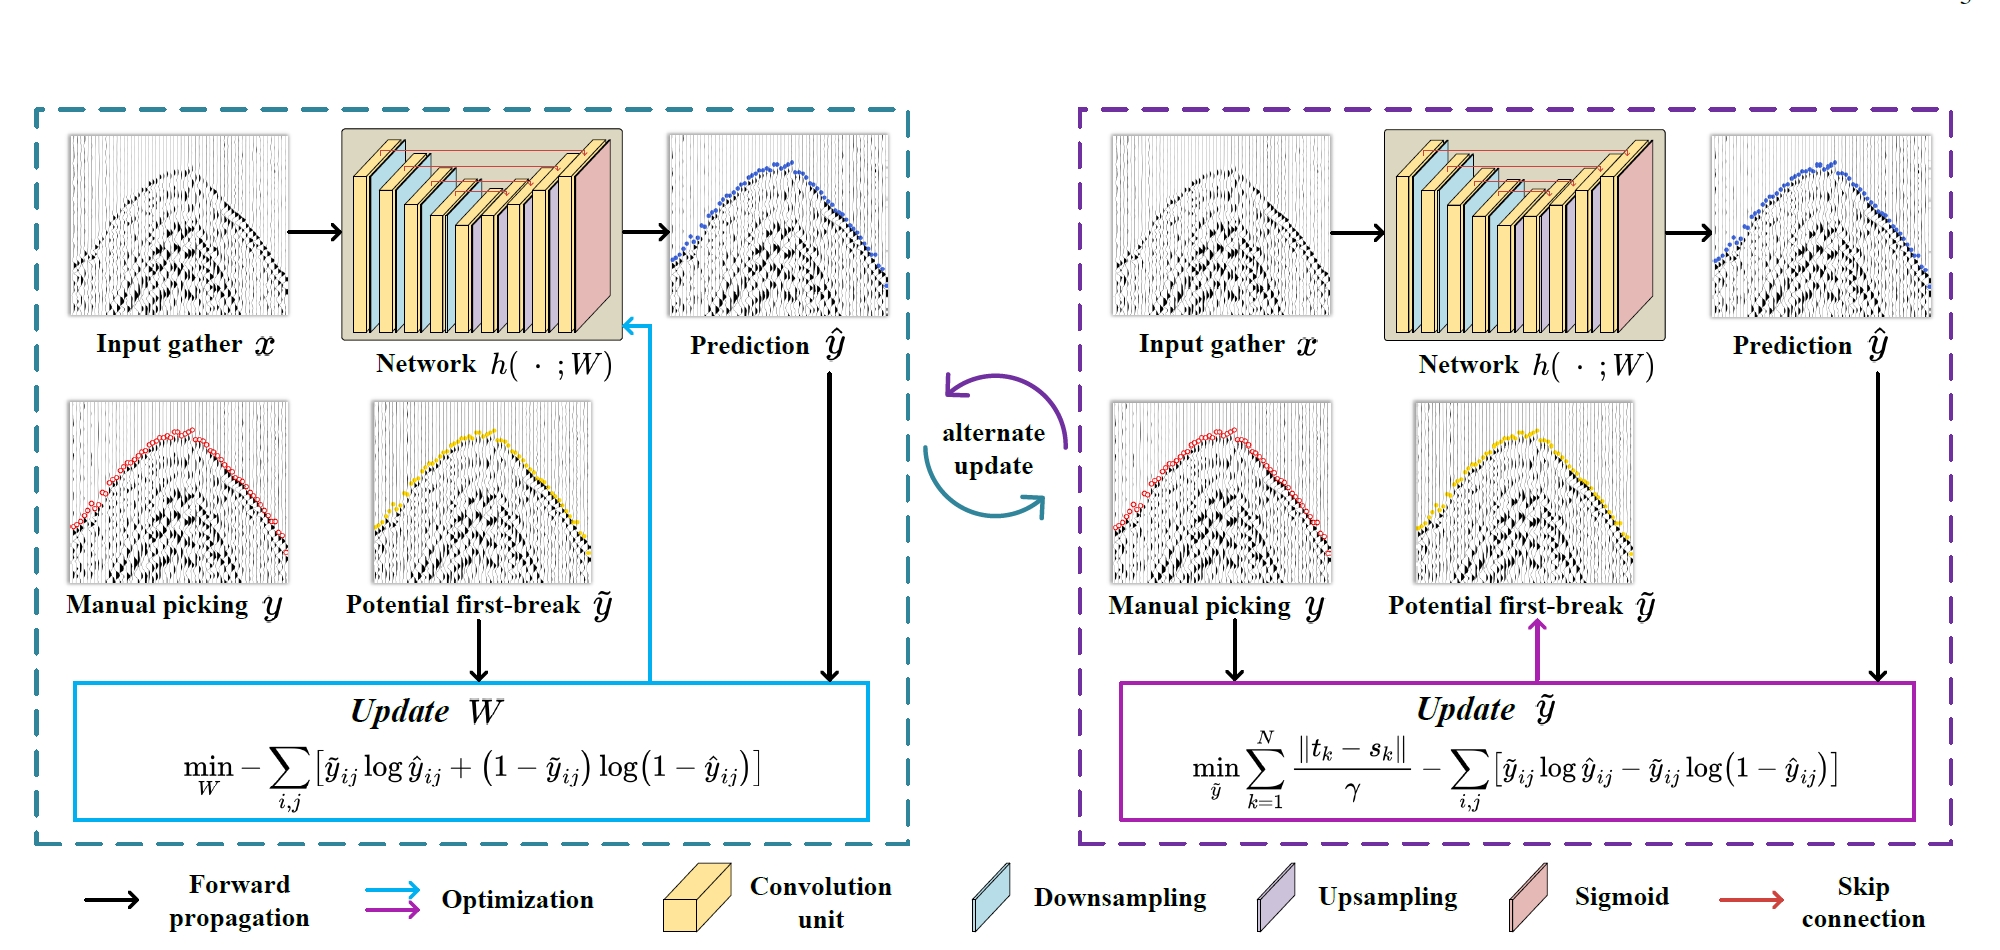
Simultaneous Automatic Picking and Manual Picking Refinement for First-Break
IEEE Transactions on Geoscience and Remote Sensing (TGRS), 62, pp. 1-12, 2024.
Haowen Bai, Zixiang Zhao, Jiangshe Zhang*, Yukun Cui, Chunxia Zhang*, Zhenbo Guo, Yongjun Wang
- Propose a novel approach that jointly optimizes label refinement and first-break picking performance in microseismic data by integrating a latent variable representation of true first-break times into a probabilistic model.提出一种新方法:把真实初至时间作为隐变量引入概率模型,联合优化微地震数据的标签修正和初至拾取。
BibTeX
@article{bai2024simultaneous,
  title   = {Simultaneous Automatic Picking and Manual Picking Refinement for First-Break},
  author  = {Bai, Haowen and Zhao, Zixiang and Zhang, Jiangshe and Cui, Yukun and Zhang, Chunxia and Guo, Zhenbo and Wang, Yongjun},
  journal = {IEEE Transactions on Geoscience and Remote Sensing},
  volume  = {62},
  pages   = {1--12},
  year    = {2024},
  doi     = {10.1109/tgrs.2024.3400977}
}
Collaborative Works合作论文
-
NeurIPS 2025(Spotlight) A Unified Solution to Video Fusion: From Multi-Frame Learning to Benchmarking.
Neural Information Processing Systems (NeurIPS), 2025.
Zixiang Zhao, Haowen Bai, Bingxin Ke, Yukun Cui, Lilun Deng, Yulun Zhang, Kai Zhang, Konrad Schindler
Project Page | Paper | ArXiv | CodeBibTeX
@inproceedings{zhao2025unified, title = {A Unified Solution to Video Fusion: From Multi-Frame Learning to Benchmarking}, author = {Zhao, Zixiang and Bai, Haowen and Ke, Bingxin and Cui, Yukun and Deng, Lilun and Zhang, Yulun and Zhang, Kai and Schindler, Konrad}, booktitle = {Advances in Neural Information Processing Systems}, volume = {38}, pages = {142598--142629}, year = {2025}, doi = {10.52202/085713-4281} } -
ICCV 2025Hipandas: Hyperspectral Image Joint Denoising and Super-Resolution by Image Fusion with the Panchromatic Image
IEEE/CVF International Conference on Computer Vision (ICCV), 2025.
Shuang Xu, Zixiang Zhao, Haowen Bai, Chang Yu, Jiangjun Peng, Xiangyong Cao, Deyu Meng
Paper | ArXiv | CodeBibTeX
@inproceedings{xu2025hipandas, title = {Hipandas: Hyperspectral Image Joint Denoising and Super-Resolution by Image Fusion with the Panchromatic Image}, author = {Xu, Shuang and Zhao, Zixiang and Bai, Haowen and Yu, Chang and Peng, Jiangjun and Cao, Xiangyong and Meng, Deyu}, booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV)}, pages = {12002--12011}, year = {2025}, doi = {10.1109/iccv51701.2025.01116} } -
ICML 2024Image fusion via vision-language model
Forty-first International Conference on Machine Learning (ICML), 2024.
Zixiang Zhao, Lilun Deng, Haowen Bai, Yukun Cui, Zhipeng Zhang, Yulun Zhang, Haotong Qin, Dongdong Chen, Jiangshe Zhang, Peng Wang, Luc Van Gool
Project Page | Paper | ArXiv | CodeBibTeX
@inproceedings{zhao2024image,
  title     = {Image Fusion via Vision-Language Model},
  author    = {Zhao, Zixiang and Deng, Lilun and Bai, Haowen and Cui, Yukun and Zhang, Zhipeng and Zhang, Yulun and Qin, Haotong and Chen, Dongdong and Zhang, Jiangshe and Wang, Peng and Van Gool, Luc},
  booktitle = {Proceedings of the 41st International Conference on Machine Learning},
  series    = {Proceedings of Machine Learning Research},
  volume    = {235},
  pages     = {60749--60765},
  publisher = {PMLR},
  year      = {2024}
}
-
CVPR 2024Equivariant multi-modality image fusion
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024.
Zixiang Zhao, Haowen Bai, Jiangshe Zhang, Yulun Zhang, Kai Zhang, Shuang Xu, Dongdong Chen, Radu Timofte, Luc Van Gool
Paper | ArXiv | CodeBibTeX
@inproceedings{zhao2024equivariant,
  title     = {Equivariant Multi-Modality Image Fusion},
  author    = {Zhao, Zixiang and Bai, Haowen and Zhang, Jiangshe and Zhang, Yulun and Zhang, Kai and Xu, Shuang and Chen, Dongdong and Timofte, Radu and Van Gool, Luc},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  pages     = {25912--25921},
  year      = {2024},
  doi       = {10.1109/cvpr52733.2024.02448}
}
-
ICCV 2023(Oral) DDFM: denoising diffusion model for multi-modality image fusion
IEEE/CVF International Conference on Computer Vision (ICCV), 2023.
Zixiang Zhao, Haowen Bai, Yuanzhi Zhu, Jiangshe Zhang, Shuang Xu, Yulun Zhang, Kai Zhang, Deyu Meng, Radu Timofte, Luc Van Gool
Paper | ArXiv | CodeBibTeX
@inproceedings{zhao2023ddfm,
  title     = {DDFM: Denoising Diffusion Model for Multi-Modality Image Fusion},
  author    = {Zhao, Zixiang and Bai, Haowen and Zhu, Yuanzhi and Zhang, Jiangshe and Xu, Shuang and Zhang, Yulun and Zhang, Kai and Meng, Deyu and Timofte, Radu and Van Gool, Luc},
  booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV)},
  pages     = {8048--8059},
  year      = {2023},
  doi       = {10.1109/iccv51070.2023.00742}
}
-
CVPR 2023CDDfuse: Correlation-Driven Dual-branch feature decomposition for multi-modality image fusion
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023.
Zixiang Zhao, Haowen Bai, Jiangshe Zhang, Yulun Zhang, Shuang Xu, Zudi Lin, Radu Timofte, Luc Van Gool
Paper | ArXiv | CodeBibTeX
@inproceedings{zhao2023cddfuse,
  title     = {CDDFuse: Correlation-Driven Dual-Branch Feature Decomposition for Multi-Modality Image Fusion},
  author    = {Zhao, Zixiang and Bai, Haowen and Zhang, Jiangshe and Zhang, Yulun and Xu, Shuang and Lin, Zudi and Timofte, Radu and Van Gool, Luc},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  pages     = {5906--5916},
  year      = {2023},
  doi       = {10.1109/cvpr52729.2023.00572}
}
-
CVPRW 2023Deep convolutional sparse coding networks for interpretable image fusion
IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), 2023.
Zixiang Zhao, Jiangshe Zhang, Haowen Bai, Yicheng Wang, Yukun Cui, Lilun Deng, Kai Sun, Chunxia Zhang, Junmin Liu, Shuang Xu
Paper | CodeBibTeX
@inproceedings{zhao2023deep,
  title     = {Deep Convolutional Sparse Coding Networks for Interpretable Image Fusion},
  author    = {Zhao, Zixiang and Zhang, Jiangshe and Bai, Haowen and Wang, Yicheng and Cui, Yukun and Deng, Lilun and Sun, Kai and Zhang, Chunxia and Liu, Junmin and Xu, Shuang},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Workshops},
  pages     = {2369--2377},
  year      = {2023},
  doi       = {10.1109/cvprw59228.2023.00234}
}
🌐 Services
Conference Reviewer:
- CVPR, ICCV, ECCV, AAAI, NeurIPS, WACV, …
Journal Reviewer:
- International Journal of Computer Vision (IJCV)
- IEEE Transactions on Image Processing (TIP)
- IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)
- Information Fusion
- ISPRS Journal of Photogrammetry and Remote Sensing
- …
🌐 学术服务
会议审稿人:
- CVPR、ICCV、ECCV、AAAI、NeurIPS、WACV 等
期刊审稿人:
- International Journal of Computer Vision (IJCV)
- IEEE Transactions on Image Processing (TIP)
- IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)
- Information Fusion
- ISPRS Journal of Photogrammetry and Remote Sensing
- ……